(Modified:
2026-10-21)
— Written by
SimeonOnSecurity— 11 min read
Wire Hermes Agent and other agents to models you control through one private endpoint, route each request to the right local or cloud model, and keep keys and budgets under your own policy.
(Modified:
2026-10-21)
— Written by
SimeonOnSecurity— 12 min read
Put one OpenAI-compatible broker in front of Ollama, vLLM, llama.cpp, and Strata. Learn lazy loading, idle unload, pools, failover, retries, and non-loading health checks.
(Modified:
2026-10-21)
— Written by
SimeonOnSecurity— 11 min read
Send one auto request and let the broker, not the agent, pick a local GPU model or a remote premium model using capability filtering, cost tiers, cascade, latency budgets, and placement pinning.
(Modified:
2026-10-21)
— Written by
SimeonOnSecurity— 10 min read
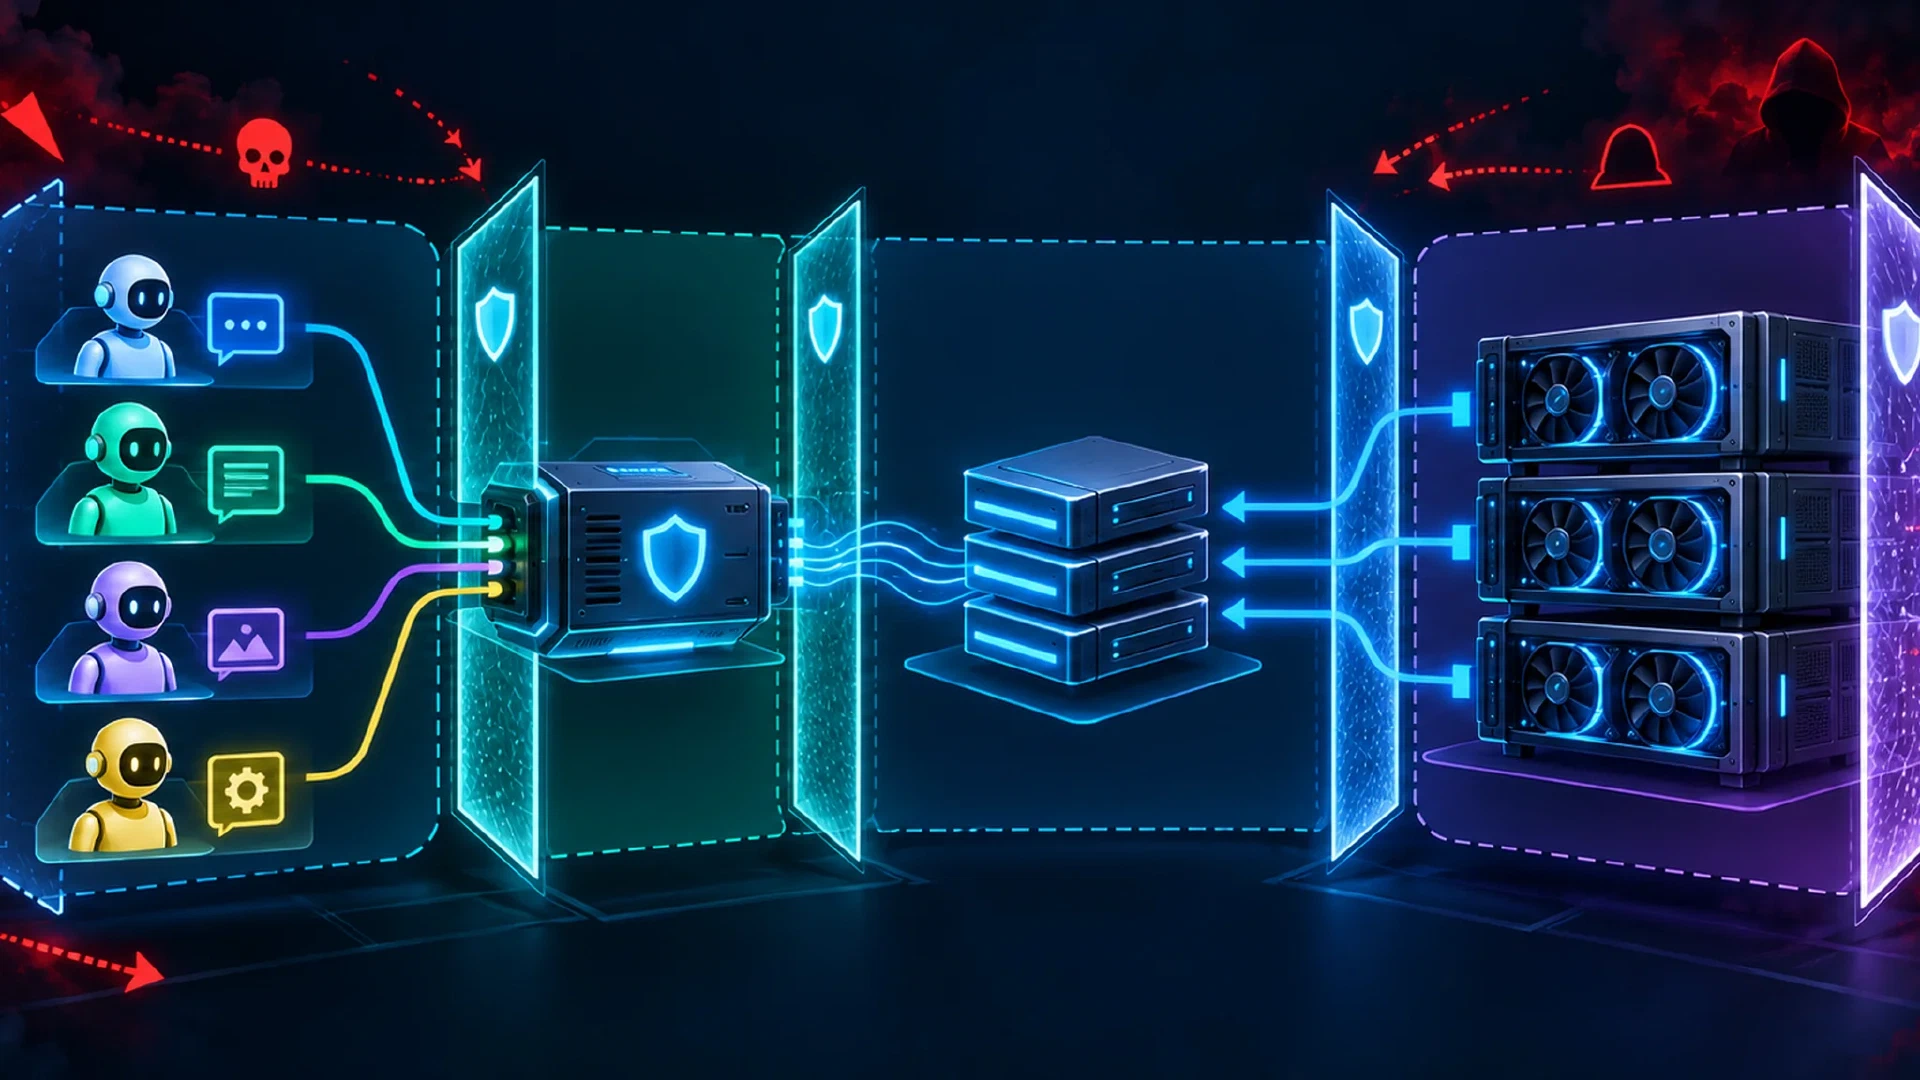
Map the real attack surface of a local AI agent stack: agents, a Tailscale private edge, an OpenAI-compatible broker, and GPU backends. See which controls hold in code and what stays unsolved.