Compare local model variants by completed answers, capability retention, context use, quantization, and practical VRAM fit.
#local LLM
#vram
#quantization
#ollama
#qwen3.8
Build a home lab in ten practical stages, from network-wide DNS filtering to local AI, with hardware, costs, skills, and tradeoffs for each level.
#Home Lab
#docker
#Proxmox
#Tailscale
#ollama
My Hermes model recommendations from long-context, tool, streaming, and vision tests on RTX 5060 Ti, RTX 2000E Ada, RTX 3060 Ti, and RTX 3070 systems.
#hermes agent
#RTX 5060 Ti
#long context
#llama.cpp
#ollama
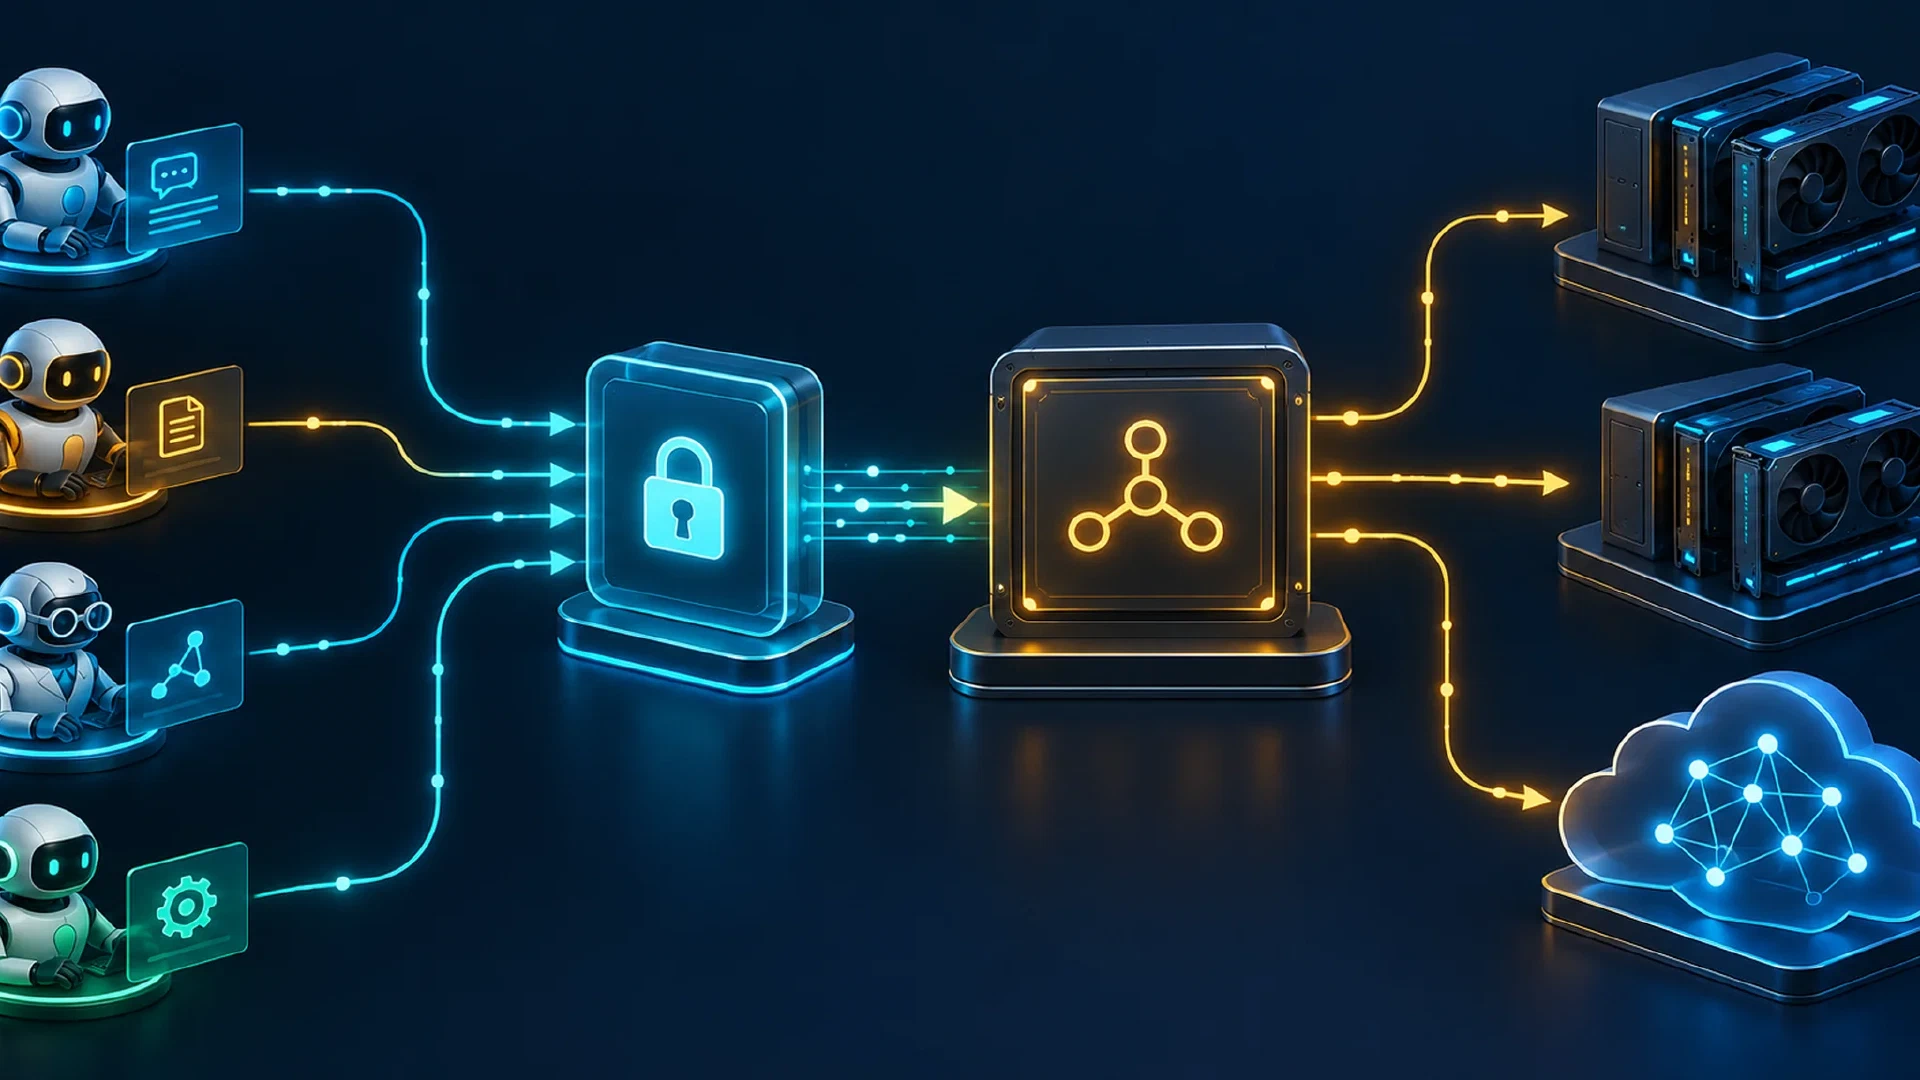
Wire Hermes Agent and other agents to models you control through one private endpoint, route each request to the right local or cloud model, and keep keys and budgets under your own policy.
#hermes agent
#local ai
#openai compatible broker
#Tailscale Aperture
#local LLM
See a verified lazy local AI fleet and its staged T0 to T4 control plane with Hermes, LiteLLM, Tailscale Aperture, and Pearl mining.
A tiered agent fleet sends each task to an appropriate model while idle GPUs return to mining #hermes agent
#Tailscale Aperture
#Tailscale
#llama.cpp
#ollama