Lesson 3: The OpenAI-Compatible AI Broker: One Endpoint for Every Local Model
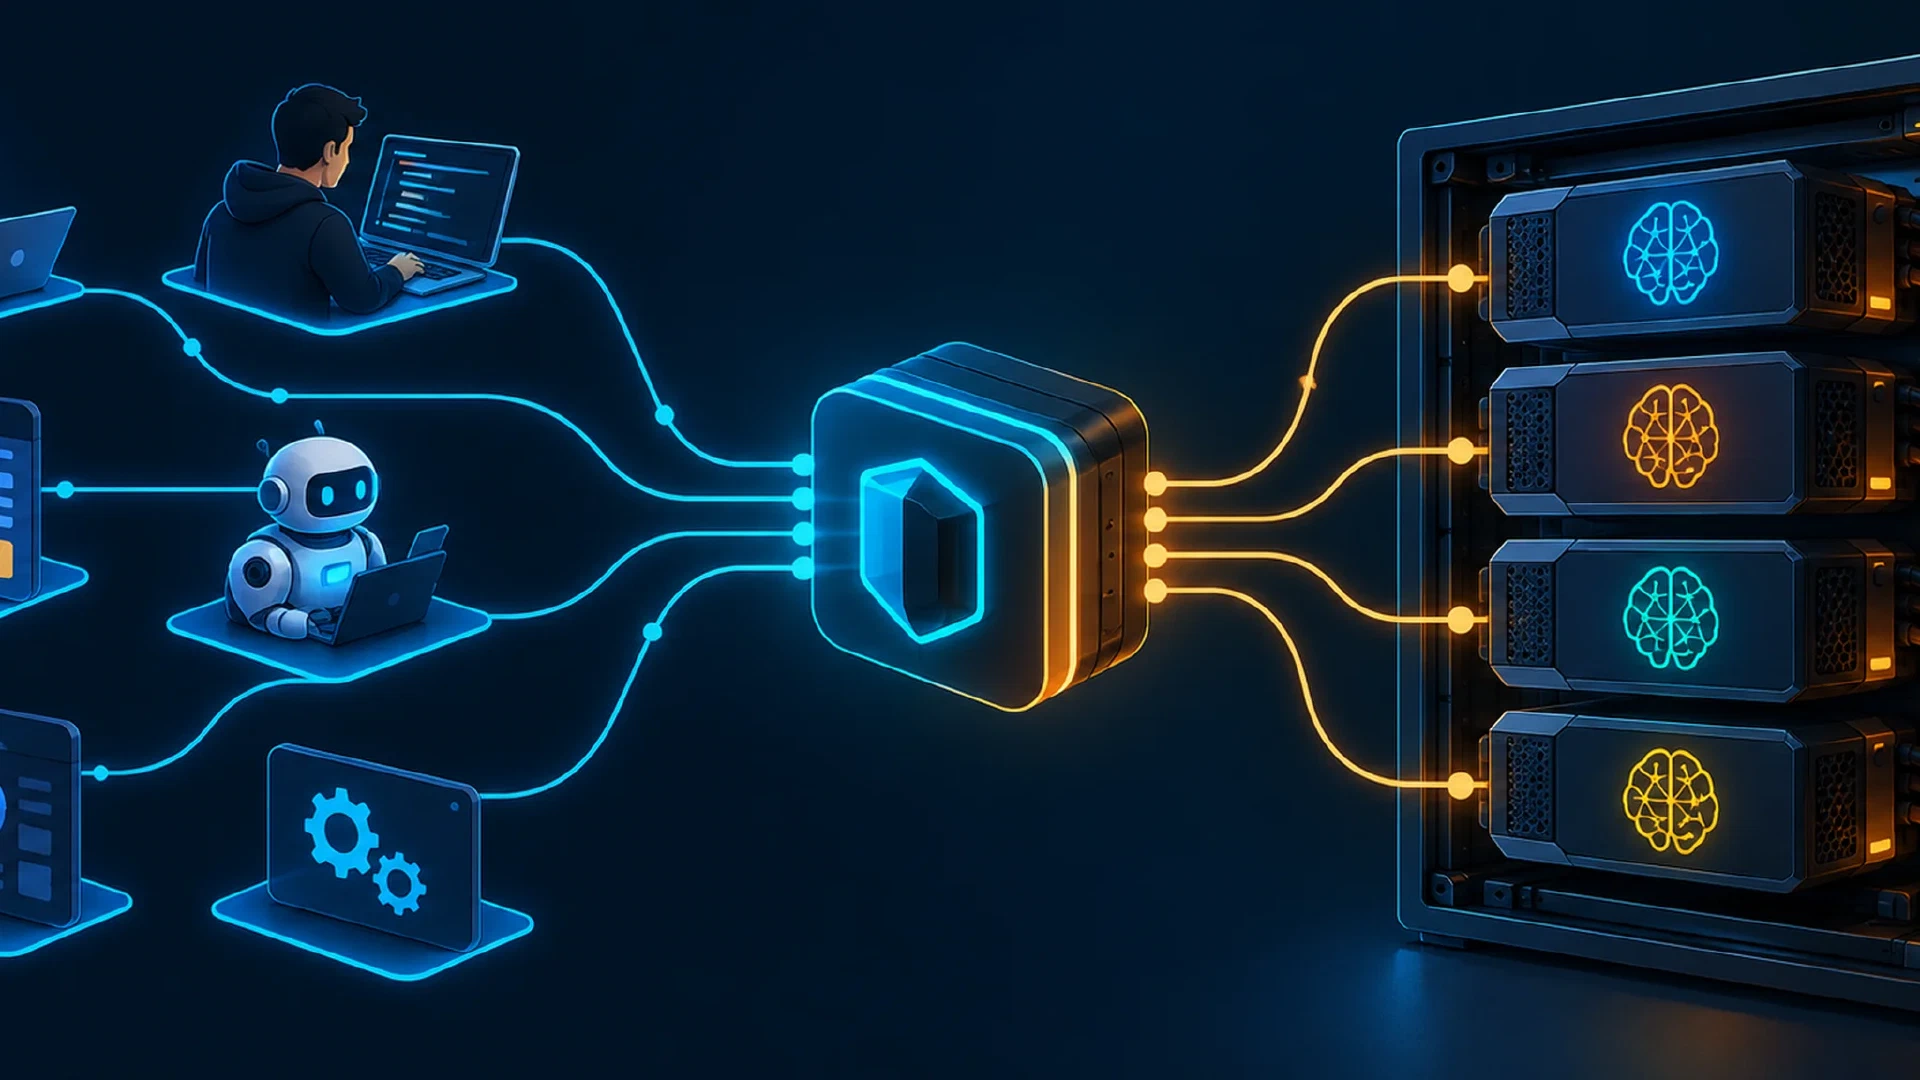
Table of Contents
Return to the Hermes Agent and Local AI Course
Introduction
An OpenAI-compatible broker is a reverse proxy that puts one base URL in front of many model runtimes. Your agents send the same OpenAI-wire request to one endpoint, and the broker decides which backend serves it, loads the model on demand, retries around a dead host, and unloads the model once it goes idle.
This guide answers one question: why put a broker between your agents and your inference runtimes, and how does it behave once requests start flowing? You will see where the broker sits in the stack, how it loads and unloads models, how pools and failover work, and how to stand a minimal broker up in front of a single backend.
The reference implementation throughout is
backend-agnostic-broker
, an open-source project that ships as a container image. Every behavior below was read from its v0.6.0 documentation, and the worked example near the end was run against its built-in fake backend.
Key Takeaways
- One base URL fronts every runtime. Agents speak the OpenAI wire protocol to the broker, and the broker owns the choice of backend.
- Models load lazily and unload on idle. A model loads only when a request selects it, and a background sweep unloads it after an idle timeout.
- Failover never crosses to a different model. The broker retries equivalent members of the same pool, so a request for one model never silently returns another.
- The registry is the single source of truth. Model names, tags, cost tiers, placement labels, and pool membership all live in one YAML file.
- Health checks never load a model. Liveness probes and status endpoints report backend health without pulling weights into memory.
Before You Begin
You need the following to follow along:
- A GPU host running at least one model runtime. The broker supports Ollama, vLLM, llama.cpp, and Strata. To pick one, read the sibling comparison on Ollama, vLLM, llama.cpp, and Strata backends .
- Docker or a Python environment to run the broker. The project publishes container images to GHCR in two flavors covered below.
- Comfort editing YAML and reading HTTP request and response bodies.
Estimated time: 20 to 30 minutes to read and run the minimal example. Difficulty: intermediate.
This guide tracks the broker at v0.6.0 as documented in October 2026. Configuration keys and image sizes reflect that release. Re-check them against the current docs before a production rollout.
Where the Broker Sits
This series builds a private stack where agents reach models they control. The broker is the middle layer.
Agents -> Aperture (private edge) -> OpenAI-compatible broker -> backends
The broker owns backend selection, model lifecycle, pools, retries, and per-key budgets. The layer in front of it, Tailscale Aperture , is the private edge that gives each caller a tailnet identity and keeps the whole stack off the public internet. A public edge for anonymous internet traffic is out of scope here, where the usual pick is a public-facing proxy such as LiteLLM.
Key Takeaway: The agent sends one request to one URL. Everything about which model runs, where, and how it recovers from failure lives inside the broker.
What the Broker Does
The broker accepts an OpenAI-wire request, reads the model name from the body, routes to the matching backend, and streams the response back. It presents the OpenAI-compatible surface your SDKs already expect.
The endpoints it serves, verified against the v0.6.0 docs and exercised in part during testing:
| Endpoint | Purpose |
|---|---|
GET /v1/models | List the models the broker serves, including pool members |
POST /v1/chat/completions | Chat requests, streaming and non-streaming |
POST /v1/completions | Legacy text completions |
POST /v1/responses | OpenAI Responses API surface |
POST /v1/embeddings | Embedding requests |
GET /healthz | Liveness, returns broker status and version |
GET /status | Per-model lifecycle and backend health |
Because the surface matches the OpenAI API, an existing client points at the broker by changing one base URL. No request format changes.
Lazy Load and Idle Unload
The broker does not hold every model in memory. A model stays unloaded until a request selects it by name. The first request pays the load cost, and later requests hit the resident model.
Idle models do not stay resident forever. A background sweep runs on an interval set by idle_sweep_interval_seconds and unloads any model past its per-model idle_timeout_seconds, which defaults to 300 seconds. (Verified against docs.)
When more models are requested than memory allows, the broker evicts the least recently used idle model once the resident count passes BROKER_MAX_LOADED_MODELS. If every resident model is busy, a new load request raises a concurrency limit error instead of thrashing memory. (Verified against docs.)
Lazy loading has a strict rule that defines the broker’s whole character: a request for one model never silently returns a different model. If the selected model cannot load, the request fails. The broker never falls back to whatever happens to be warm.
The Lifecycle State Machine
Every model moves through an explicit set of states. Illegal transitions raise a LifecycleError rather than leaving a model in an undefined condition. (Verified against docs.)
| State | Meaning |
|---|---|
unloaded | Not resident, holding no GPU or system memory |
loading | Startup command running or weights loading into memory |
ready | Resident and idle, available for the next request |
busy | Serving one or more in-flight requests |
unloading | Shutting down after an idle timeout or an eviction |
failed | Load or health failure, benched from routing |
stopping | Broker shutdown in progress |
A model in failed is benched, not retried in a loop. The broker brings it back through a half-open trial, covered in the retries section below.
The Registry Is the Single Source of Truth
Every model the broker serves is one entry in a registry YAML file. One entry names a public alias, the backend that runs it, the real runtime_model_id the backend expects, and a set of control fields.
The control fields decide routing and lifecycle without any logic in the agent:
tagsdescribe capability, such asgeneral,cheap,fast,chat, orreasoning.cost_tierranks price from 1 (cheapest) to 5 (most expensive).prioritybreaks ties between equally capable candidates.placementcarries data-residency labels for fail-closed pinning.poolgroups several entries under one public name.pricingsets a per-million-token cost used by per-key budgets.
Those last fields feed the auto router and per-key governance, each its own deep dive. For how the broker, not the agent, chooses local against cloud from this registry data, see
the local and cloud auto-router
. For virtual keys, budgets, and placement enforcement, see
secure broker governance
.
Best Practice: Add, alias, and retier a model by editing one registry entry. Clients keep sending the same model name, and nothing changes on their side.
Pools: One Model Name, Many Hosts
When several registry entries share a pool name, clients see one public model, and the broker spreads requests across the pool members. The GET /v1/models response reports pool_size and pool_members so you confirm the shape. A standalone alias cannot collide with a pool name, and the broker fails fast at load if it does. (Verified against docs.)
Pool routing picks a member through one of four strategies, set with BROKER_ROUTE_STRATEGY:
| Strategy | How it picks a member | Use when |
|---|---|---|
sticky (default) | Hashes the caller so one session keeps hitting one member | You want prompt-cache reuse and warm state per caller |
least_busy | Chooses the member with the fewest in-flight requests | You want the best tail latency under load |
round_robin | Rotates to the next member in order | You want an even, predictable spread |
cache_aware | Scores prefix-cache match minus relative load | Members share long prompt prefixes, an opt-in strategy |
The one rule that holds across every strategy: failover never crosses to a different model. When a pool member fails, the broker retries an equivalent member of the same pool, never a model with different weights. For streaming requests, failover happens before the first byte reaches the client, so a half-streamed answer is never stitched together from two hosts. (Verified against docs.)
Retries, Backoff, and Cooldowns
A transient backend error should not surface to the agent as a hard failure. The broker retries with capped-exponential backoff and full jitter, the same pattern AWS documents for its SDKs. The attempt count and timing come from BROKER_RETRY_MAX_ATTEMPTS, BROKER_RETRY_BACKOFF_BASE_MS, and BROKER_RETRY_BACKOFF_MAX_MS. Setting the attempt count to zero reverts to a single legacy failover pass. (Verified against docs.)
Repeated failures from one member trip a per-member cooldown, a circuit breaker. After a configured number of failures the member is benched, then given a single half-open trial request before it returns to rotation. The reliability-v2 policy adds an ejection cap, exponential cooldown growth, and per-error rules. One rule matters most: a 4xx client error is never retried or benched, because a bad request will fail the same way on every member. (Verified against docs.)
Common Mistake: Treating a 4xx as a backend fault. A malformed request or an unknown model is the client’s error. The broker returns it straight through instead of burning retries on it.
Health Without Loading a Model
A health check that loads a model to prove the model works would defeat lazy loading. The broker separates liveness from model readiness. None of its health paths pull weights into memory. (Verified against docs.)
GET /healthzreturns broker status and version with no backend contact.GET /healthz/backendsreports each backend’s reachability.GET /statuscarries ahealthyfield per model alongside its lifecycle state.GET /api/pspasses through to Ollama’s process list where that backend is present.- A background liveness probe checks backends on an interval set by the
BROKER_HEALTH_PROBE_*keys, defaulting to 30 seconds.
This lets an orchestrator or a monitoring probe ask “is the broker up and are its backends reachable” without waking a cold model and paying a load cost on every poll.
A Minimal Broker Over One Backend
Here is the smallest useful setup: one broker in front of one backend. This example was run against the broker’s built-in fake backend, which echoes input and exercises the full request path (auth, lifecycle, routing, and streaming) with no GPU. Swap backend and runtime_model_id for a real runtime in production.
First, the registry. Save it as registry.yaml:
models:
  - alias: echo-local
    backend: fake            # prod: ollama, vllm, llamacpp, or strata
    runtime_model_id: fake-echo-v1
    context_limit: 8192
    output_limit: 2048
    idle_timeout_seconds: 60
    supports_streaming: true
    tags: [general, cheap, fast]
Then start the broker with auth on and the fake backend enabled:
BROKER_AUTH_ENABLED=true \
  BROKER_API_KEYS='["YOUR_API_KEY"]' \
  BROKER_ENABLED_BACKENDS='["fake"]' \
  BROKER_REGISTRY_PATH=registry.yaml \
  python -m broker
Confirm the broker is live. This path loads no model:
curl http://<GPU_HOST>:<BROKER_PORT>/healthz
Expected output:
{"status":"ok","version":"0.6.0"}
List the models with a valid key. A request with no key returns 401:
curl http://<GPU_HOST>:<BROKER_PORT>/v1/models \
  -H "Authorization: Bearer YOUR_API_KEY"
The response lists echo-local. Now send a chat request and watch the broker route it:
curl http://<GPU_HOST>:<BROKER_PORT>/v1/chat/completions \
  -H "Authorization: Bearer YOUR_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model":"echo-local","messages":[{"role":"user","content":"ping"}]}'
What the test showed: GET /healthz returned the status and version above. GET /v1/models returned 401 without a key and listed echo-local with a key. The chat request returned a chat.completion object with a usage block, and setting "stream": true produced chat.completion.chunk frames with incremental content. The model loaded on the first selecting request, served it, and unloaded after its 60-second idle timeout. (Tested against the fake backend.)
Expected Result: One base URL answers OpenAI-wire requests, enforces the API key, and manages the model’s lifecycle without the client knowing which backend ran.
Lean and Bundled Container Images
The project publishes two GHCR image variants. The difference is whether a small classifier model is baked in for the auto router. (Image sizes are documented, not independently rebuilt for this guide.)
| Image tag | Contents | Documented size |
|---|---|---|
:latest / :X.Y.Z | Broker only, heuristic router | about 272 MB |
:latest-llm / :X.Y.Z-llm | Broker plus a CPU llama.cpp classifier and a quantized router model | about 1.35 GB |
The lean image runs the auto router through a pure-Python heuristic. The -llm image mounts a small quantized model at a fixed path so the router runs a constrained classifier instead. If that file is missing, the router falls back to the heuristic. For most single-endpoint setups, the lean image is enough, and the router deep dive covers when the bundled image earns its size.
Backends It Fronts, and One It Does Not
The broker’s backend set is fake, ollama, vllm, llamacpp, and strata. Its generic HTTP adapter fronts any OpenAI-compatible HTTP endpoint, with an optional broker-managed process. (Verified against docs.)
One boundary matters for planning. In v0.6.0 there is no hosted-frontier adapter for OpenAI or Anthropic as a paid third-party API. A “cloud” model in this broker is a remote self-hosted OpenAI-compatible endpoint, such as vLLM on a cloud GPU host, reached by its base URL. The broker fronts runtimes you operate, not a metered public API. Keep that distinction when you plan a local-and-remote mix.
Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| HTTP 401 on every call | Auth enabled, missing or wrong bearer key | Send Authorization: Bearer YOUR_API_KEY matching BROKER_API_KEYS |
| HTTP 404 for a model name | The alias is not in the registry | Add the model as a registry entry and reload |
| Concurrency limit error on load | Every resident model is busy at the max loaded count | Raise BROKER_MAX_LOADED_MODELS or reduce concurrent distinct models |
| A request returns a different model’s answer | This should never happen by design | File it as a bug, the broker never crosses models on failover |
| Repeated 4xx with no retry | Correct behavior, 4xx is a client error | Fix the request body or model name, the broker will not retry it |
| A member keeps dropping out of a pool | Cooldown benched it after repeated failures | Check the member’s own health, the broker retries it through a half-open trial |
| Health probe wakes models | Wrong endpoint, a load path was polled | Poll /healthz, /healthz/backends, or /status, none load a model |
Next Steps
You now have a mental model of the broker: one OpenAI-compatible endpoint, lazy loading, idle unload, pools with same-model failover, retries with cooldowns, and non-loading health checks.
- Read the series master, the Hermes Agent local AI brokerized workflow , for how the broker fits the full stack.
- Pick the runtime behind the broker with the Ollama, vLLM, llama.cpp, and Strata comparison .
- Let the broker choose local against cloud with the local and cloud auto-router .
- Add virtual keys, budgets, and placement rules with secure broker governance .
- Expose the broker privately with Tailscale Aperture .
Continue with Lesson 4: Auto-Routing Local and Cloud .