OpenRouter Provider Routing: Model Quality, Token Limits, and Real Costs
Table of Contents
OpenRouter provider routing affects which inference service answers your request. Two calls using the same model name still depend on endpoint limits, supported parameters, serving software, and routing preferences. When answers become shorter or tool calls fail, check those differences before blaming quantization.
Key Takeaways
- Precision labels describe a numerical format, not an accuracy score.
- Endpoint limits determine available context, output length, and feature support.
- Explicit routing needs a fallback policy as well as a provider preference.
- Auto Exacto improves provider selection using quality signals, with an opt-in route for requests without tools.
- Effective cost includes output, cache behavior, retries, and successful task completion.
Prerequisites: Familiarity with JSON requests and access to your application’s OpenRouter configuration. Endpoint inspection uses a public API. Sending model requests requires an API key and incurs usage charges.
Time and difficulty: About 20 minutes for an initial configuration review. Intermediate. A useful comparison across providers requires additional testing with representative prompts.
What Your Model Name Omits
A model identifier selects the requested model. The provider runs the inference service, including its model implementation, token limits, and tool-call parser. A model-level benchmark does not validate every service hosting those weights.
| Endpoint property | What to check |
|---|---|
| Context length | Space for the prompt, history, tool results, and generation |
| Maximum completion length | Output allowance for the requested task |
| Supported parameters | Tool use, structured output, sampling, and reasoning controls |
| Quantization | Reported format compared with the original release |
| Pricing | Input, output, cache reads, and applicable additional charges |
| Serving behavior | Completion quality, parsing errors, latency, and retries |
Baseline routing favors lower prices among healthy candidates. OpenRouter documents inverse-square price weighting: in its simplified example, a $1 candidate receives nine times the selection weight of a $3 candidate. This describes relative weights, not a guarantee about your next request. Explicit ordering, sorting, caching, and quality routing also affect selection. See the provider routing documentation .
Price weighting does not establish the cheapest bill for your workload. The documented example does not specify a universal input/output mixture for its price scalar. Avoid inferring a provider’s selection probability from input price alone.
Read Precision in Context
Quantization stores numerical values using a reduced representation. Its effect depends on the model, method, and inference implementation. Lower precision warrants testing, but the label alone does not demonstrate a provider changed the original weights.
GPT-OSS provides a concrete example. OpenAI’s gpt-oss-120b release documentation states its mixture-of-experts weights use MXFP4 and its evaluations used the same quantization. A four-bit label for those weights is consistent with the published release. It is not evidence of an additional provider downgrade.
Upcasting converts stored values into a wider representation. Converting an already quantized checkpoint to BF16 does not recover information discarded during quantization. Conversely, converting an originally higher-precision checkpoint to four bits introduces a separate change worth evaluating.
| Observation | Supported conclusion |
|---|---|
| Native MXFP4 checkpoint | Four-bit expert weights belong to the release |
| BF16 endpoint label | A wider reported format, without proof of better answers |
| Unknown precision | Missing metadata, without proof of hidden degradation |
| Matching precision labels | Insufficient evidence of equivalent serving behavior |
Matching labels also fail to rule out quantization differences. They omit details such as which tensors were quantized, calibration choices, and execution kernels. Test the complete endpoint instead of treating bit depth as a quality ranking.
Check the Token Budget
curl --fail --silent --show-error \
  'https://openrouter.ai/api/v1/models/openai/gpt-oss-120b/endpoints' \
  | jq '.data.endpoints[] | {
      name,
      provider_name,
      context_length,
      max_completion_tokens,
      supported_parameters,
      quantization,
      pricing
    }'
The endpoints API exposes provider-level metadata for one model. This command needs curl and jq. Inspect the
live gpt-oss-120b endpoint response
before selecting a service. Treat missing or null fields as unknown rather than unlimited. Save a dated local snapshot when comparing results.
A check on October 5, 2026 returned these advertised limits for gpt-oss-120b. These are metadata values, not measured completion lengths, and providers change them over time.
| Provider | Context tokens | Maximum completion tokens |
|---|---|---|
| DigitalOcean | 128,000 | 4,096 |
| Novita | 131,072 | 32,768 |
| Together | 131,072 | 117,964 |
Context length and output length are separate limits. A long-context model still needs sufficient room for its answer. Conversation history, system instructions, and tool definitions consume space alongside the user’s document.
Reasoning tokens also consume generation budget on supported reasoning models. A small allowance risks incomplete reasoning, little visible output, or termination before a final answer. Inspect usage and the finish reason rather than assuming every short answer reflects weaker weights. OpenRouter explains this budgeting in its reasoning-token documentation .
An explicit max_tokens gives the router a requested output length to match against provider support. Choose it from measured task needs and available context. Setting an excessive value narrows eligibility and does not guarantee a longer or better answer.
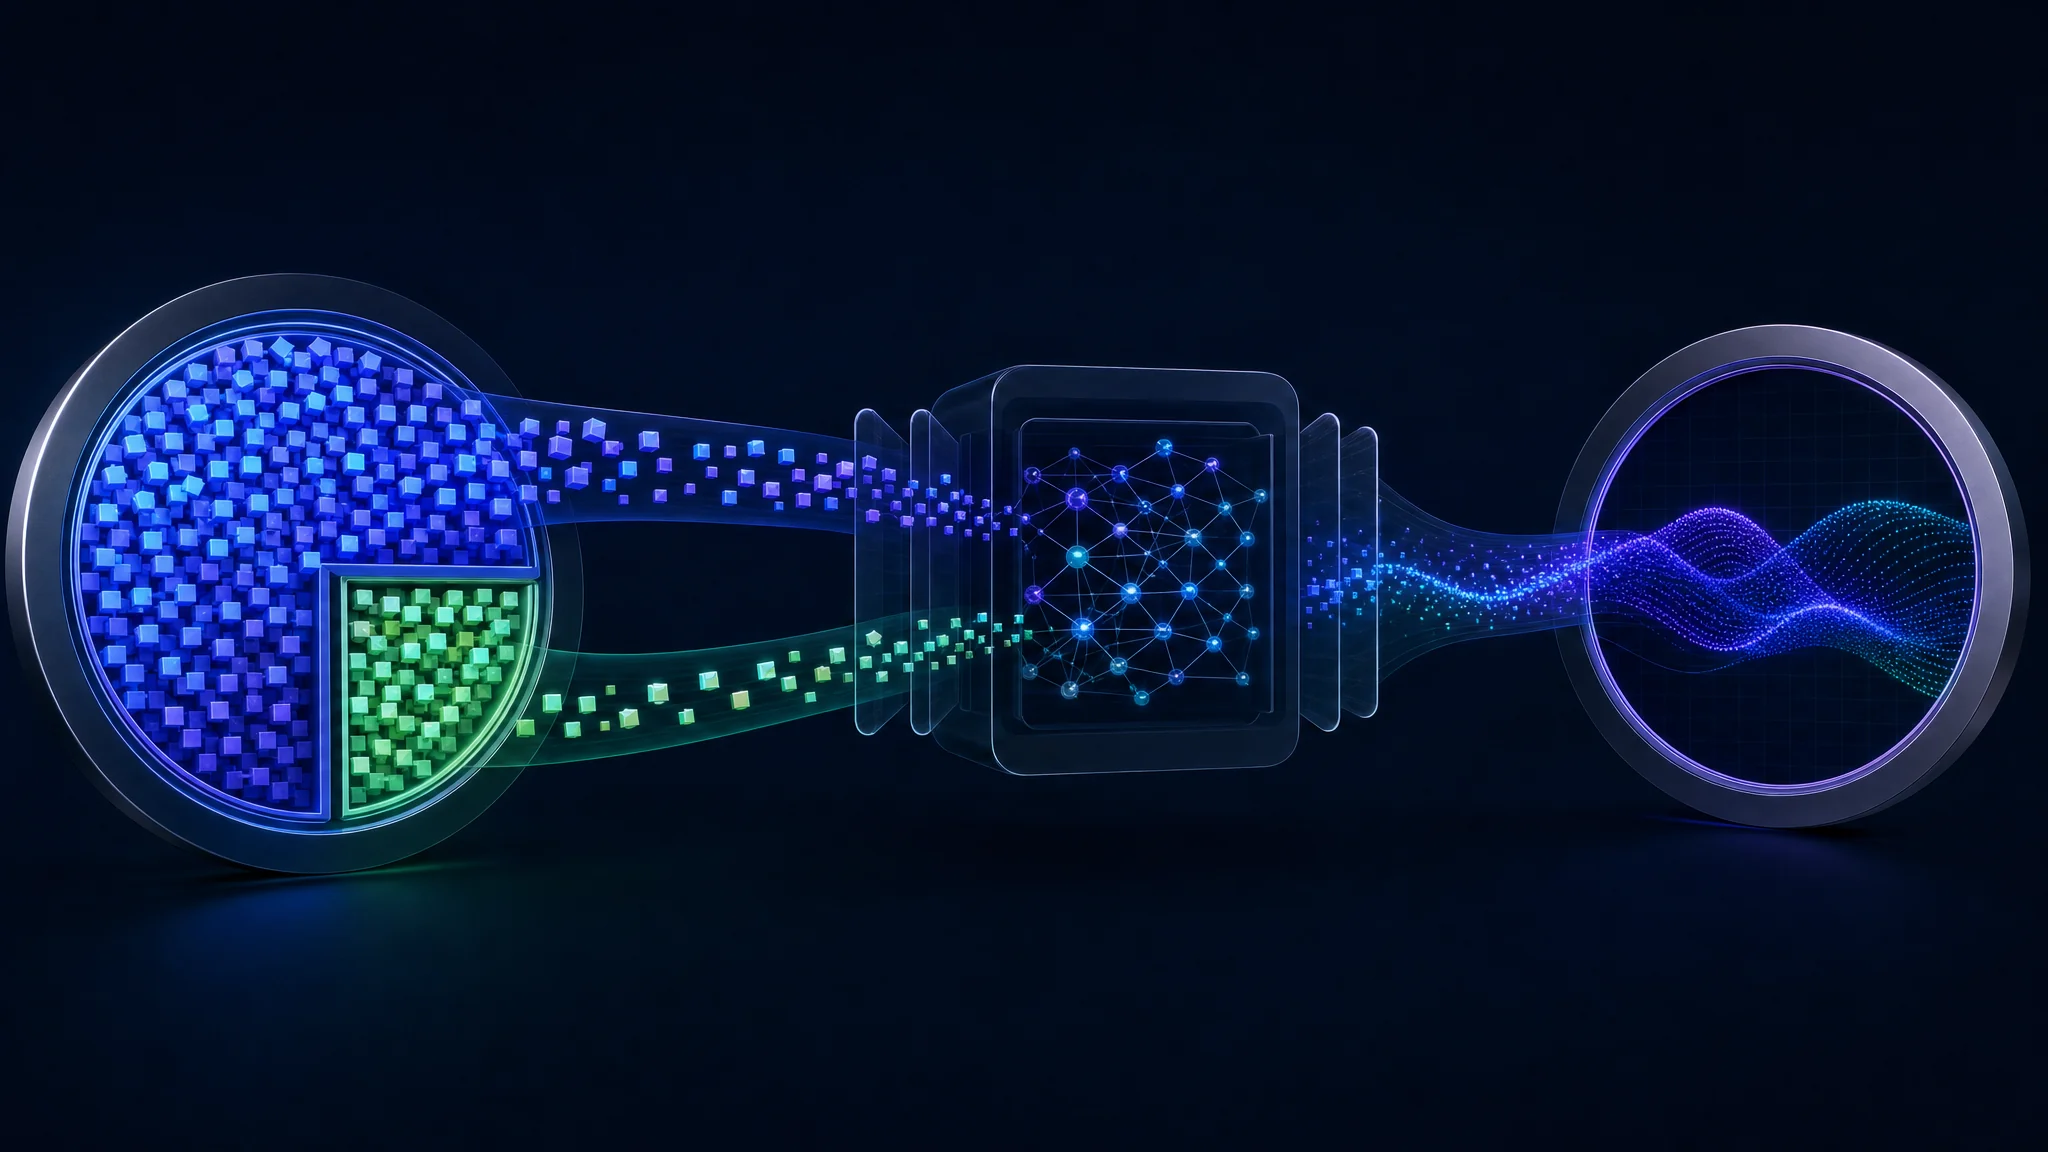
Conceptual token allocation, with reasoning and visible output sharing the completion allowance on supported providers
Require Your Parameters
{
  "model": "openai/gpt-oss-120b",
  "messages": [
    {"role": "user", "content": "Explain the failure modes of a retry loop."}
  ],
  "max_tokens": 8192,
  "provider": {
    "require_parameters": true
  }
}
require_parameters defaults to false. Under default routing, unsupported parameters do not necessarily exclude an endpoint. OpenRouter documents providers ignoring unknown parameters. Setting this field to true filters routing by declared support.
Support metadata is not a behavioral guarantee. An endpoint advertising seed support still needs reproducibility testing. A tool-capable endpoint still needs schema validation and application-level tests. The filter prevents known incompatibilities from entering the candidate set.
Pin Providers Deliberately
{
  "model": "openai/gpt-oss-120b",
  "messages": [
    {"role": "user", "content": "Summarize the supplied incident report."}
  ],
  "max_tokens": 8192,
  "provider": {
    "order": ["REPLACE_WITH_VERIFIED_PROVIDER_SLUG"],
    "allow_fallbacks": false,
    "require_parameters": true
  }
}
Replace the placeholder with a provider slug copied from the model’s provider listing. Supply the report in your real request. This template is for configuration review, not a runnable request until you replace its placeholder.
order establishes preference. By itself, it leaves fallback to other providers enabled. Pairing it with allow_fallbacks: false restricts routing to the listed providers. Expect a failed request when none satisfies the request or remains available.
Endpoint variants need attention. A base provider slug matches multiple variants under the documented matching rules. Use the specific variant slug when testing a particular service configuration. Recheck the provider reported for each response.
quantizations is an allowlist of named formats, not a numerical minimum. An array containing "fp8" selects matching FP8 endpoints. It does not automatically include BF16 or all formats with more bits. Compare the original checkpoint first, then apply this filter only when your evaluation supports the restriction.
Keep Quality Routing Enabled
{
  "model": "openai/gpt-oss-120b:exacto",
  "messages": [
    {"role": "user", "content": "Compare the two supplied incident reports."}
  ],
  "max_tokens": 8192,
  "provider": {
    "require_parameters": true
  }
}
Auto Exacto uses throughput, tool-call telemetry, and benchmarks to deprioritize underperforming providers. OpenRouter’s March 2026 announcement reports GLM-5 tool-call errors falling by 88%, with rates moving from roughly 8% toward 1%. It reports gpt-oss-120b moving from 5.6% to 3.5%.
Those are vendor-reported rollout results, not a promise for your application. Tool-call validity measures JSON, names, and schemas. A syntactically valid call still needs the correct arguments and action for the user’s task.
Requests containing tools receive Auto Exacto by default where the model has sufficient provider coverage. For other requests, :exacto opts into quality routing. The current documentation therefore supports quality routing for summarization and chat as well as tool use.
sort: "price", the :floor suffix, and an account-level default price sort opt out of Auto Exacto. Check application settings and account preferences together. Consult the
Auto Exacto documentation
before combining routing controls.
Calculate Your Workload Cost
Input price alone is an incomplete comparison. Consider these illustrative rates, expressed in dollars per million tokens. They demonstrate the arithmetic and are not current provider quotes.
| Illustrative endpoint | Input price | Output price |
|---|---|---|
| A | $0.03 | $16.00 |
| B | $0.42 | $1.32 |
Workload: 6 million input tokens + 1 million output tokens

A = 6 × $0.03 + 1 × $16.00 = $16.18
B = 6 × $0.42 + 1 × $1.32  =  $3.84

Per million combined input and output tokens:
A = $16.18 / 7 = $2.31
B =  $3.84 / 7 = $0.55
Endpoint A costs about 4.2 times as much for this mixture despite its lower input price. The 533-to-1 output/input price ratio on A is a ratio between two rates, not the user’s total cost multiplier. Different input/output proportions change the comparison.
API pricing units differ from comparison tables. The endpoint API expresses token prices per token. Multiply by one million before comparing them with the rates above.
Prompt caching introduces another variable. Cached reads, cache writes, and uncached input require separate accounting under the provider’s billing rules. Repeated text does not guarantee a cache hit. Check the reported cached-token counts and costs using the prompt caching documentation .
Routing affects cache continuity. OpenRouter documents sticky routing for caching, while manual provider order takes precedence. Auto Exacto also reorders providers and sometimes disrupts a warm cache. Compare observed cache savings against quality and retry costs before changing either policy.
Cost per accepted result is the useful application metric: divide total spend, including retries and failed attempts, by results meeting your acceptance criteria. Include any applicable non-token charges separately. A low token rate does not compensate for repeatedly unsuccessful tasks.
Diagnose an Inconsistent Answer
| Symptom | First check |
|---|---|
| Short or unfinished response | Finish reason, output allowance, reasoning usage |
| Missing document details | Submitted content, endpoint context limit, client truncation |
| Malformed tool call | Advertised support, tool schema, parsing behavior |
| Different sampling behavior | Requested parameters and declared support |
| Unexpected expense | Output volume, cache reads, retries, provider changes |
| No eligible provider | Conflicting limits, allowlists, and fallback restrictions |
Preserve the generation ID returned with the response. OpenRouter’s generation metadata API exposes provider identity, usage, cost, and finish information. A session ID groups related work, but it does not replace the generation ID for a single-request lookup.
Compare endpoints under matching conditions. Use the same prompt, tools, reasoning settings, and token budget. Repeat across several representative tasks. Separate incomplete responses, invalid tool calls, and wrong answers instead of combining them into one unexplained quality score.
Benchmark uncertainty matters. Epoch AI’s benchmarking analysis describes variation from implementations, sampling, and agent scaffolds. One disappointing answer does not establish a persistent provider defect or identify its cause.
Endpoint Routing Walkthrough
Further viewing: OpenRouter endpoint quality and routing discussion . Recheck endpoint listings before applying specific prices, limits, or provider comparisons.
Next Steps
- Inspect one model’s endpoints and record the limits relevant to your workload.
- Select a routing policy with explicit parameter requirements and fallback behavior.
- Test representative tasks against candidate endpoints and quality routing.
- Record accepted-result cost alongside latency, cache usage, and failure categories.
- Recheck after changes to model versions, serving behavior, or provider prices.
For broader AI fundamentals, continue with Basic AI Concepts . For agent permissions and validation controls, read Securing AI Systems .

Related Posts