Bounded AI Agent Loops: Checks, Retries, and Stop Rules
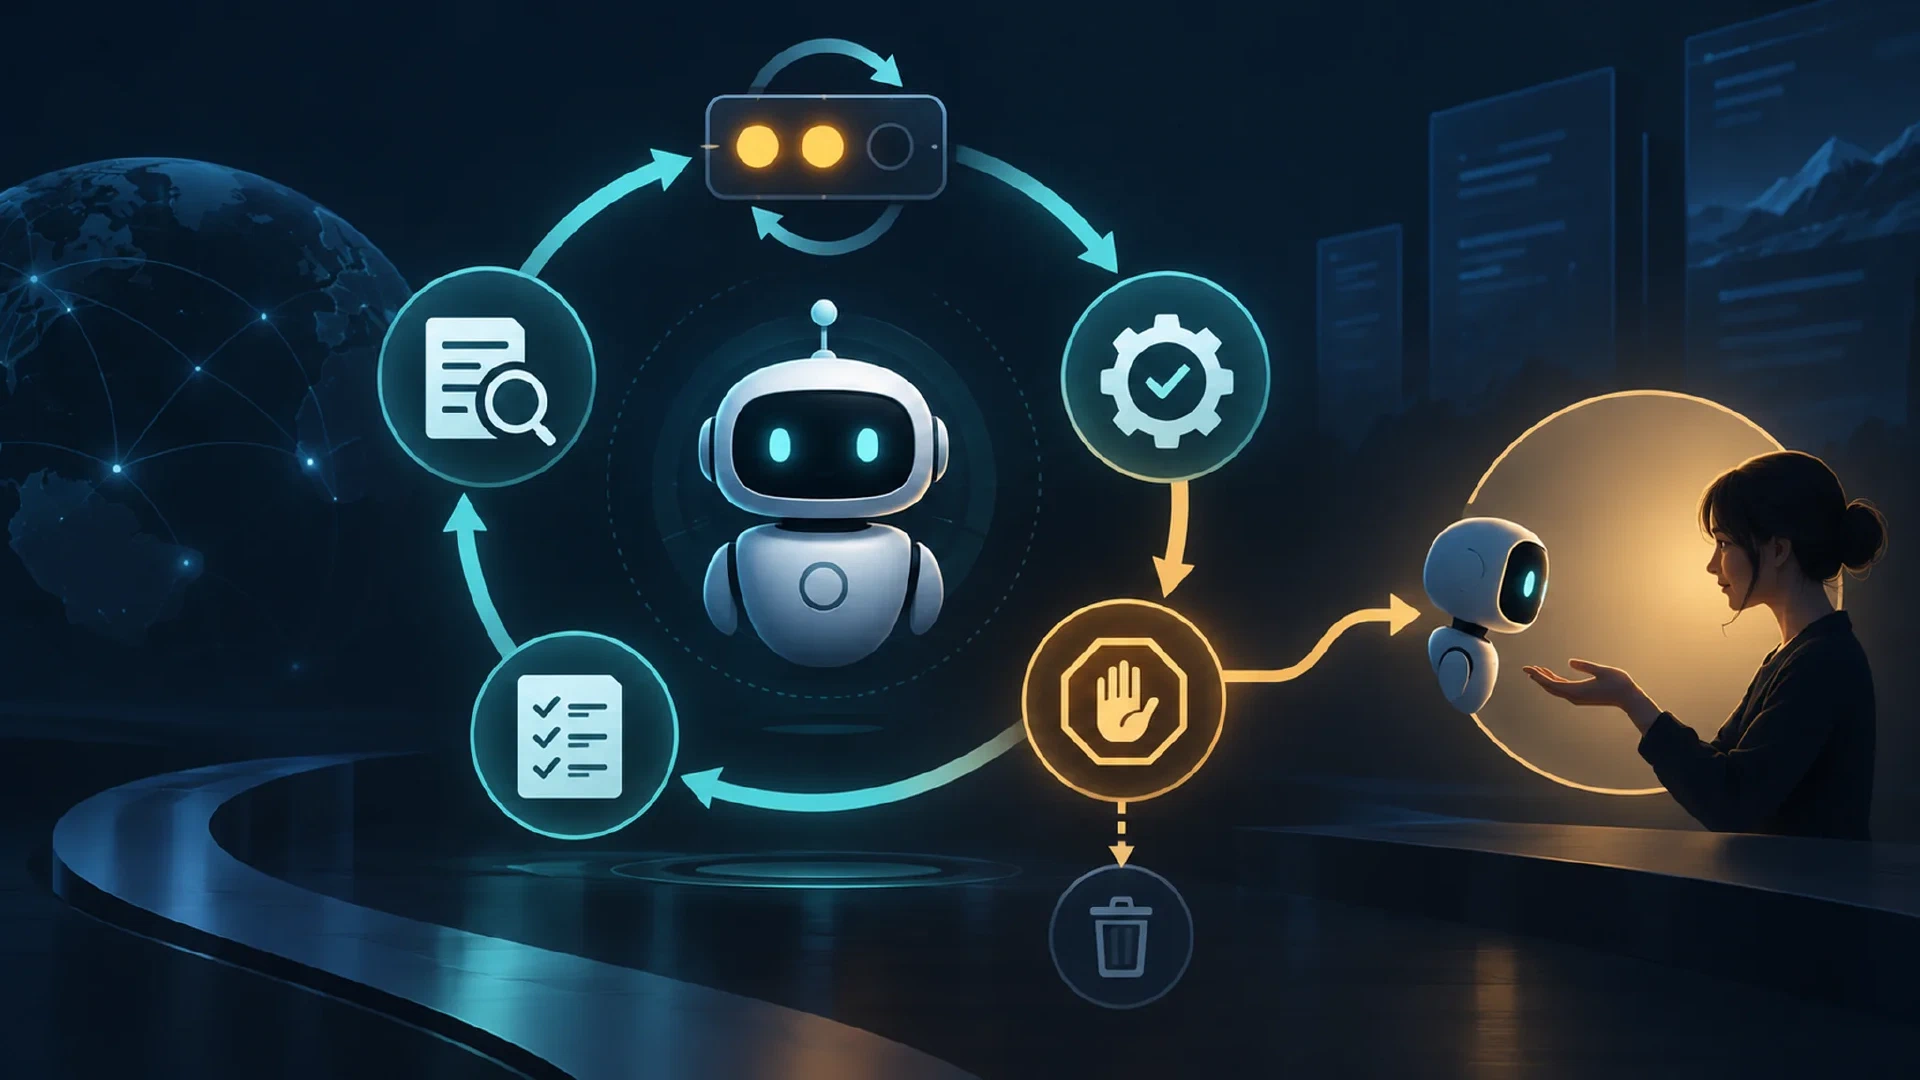
Table of Contents
Return to the Practical AI Workflow Course
A goal loop repeats work until a defined result passes or a stop rule fires. The useful loop reads current state, takes one bounded action, checks the result, and records what happened. An open-ended “keep trying” instruction has no reliable completion rule.
Learning outcome: you will run a bounded lab loop with a known failed check and record its stop decision.
Key Takeaways
- Goal: a result stated in observable terms.
- State: the current files, outputs, errors, and source revision.
- Check: a test or review tied to the goal.
- Retry budget: the maximum attempts allowed for one failure.
- Stop rule: a condition requiring an end or human decision.
Before You Begin
Prerequisites: the task packet , verification record , and delegation lesson . Set aside 45 minutes. Difficulty is intermediate. Use a fresh copy of the synthetic lab so the first failed check is known in advance.
Write the Loop Contract
For the status-filter request, set the contract before any retry:
Goal: support --status open|done without changing default output.
Source: docs/requirements.md, revision 1.
Allowed files: task_report.py and focused tests.
Checks: unit tests, counts 4/2/2, invalid value exits nonzero.
Retry budget: at most two edits after the first attempt.
Stop immediately: source conflict, unexpected file change, secret exposure,
or a failing baseline unrelated to this request.
Handoff: report final diff, commands, outputs, attempts, and unresolved issue.
The budget is a task policy, not a product default. Two retries are enough to diagnose a small lab task without hiding repeated failure. A production task needs its own risk and review choice.
Use a State Table
| Step | State to record | Decision |
|---|---|---|
| Read | Source revision and baseline result | Stop if the starting state differs |
| Act | Changed files and action taken | Reject out-of-scope edits |
| Check | Exact test and manual output | Accept or diagnose |
| Retry | Failure cause and new hypothesis | Continue only within budget |
| Handoff | Final state and next owner | Stop after pass or blocked result |
Record attempts, not only the last message. A test passing after three hidden edits leaves no useful account of what changed. Keep a short attempt log with the failure, revised hypothesis, and new evidence.
Walk Through a Failure
Illustrative first attempt: the agent adds filtering and tests. open prints 2, but --status invalid prints 0 and exits successfully. The requirement says an invalid value needs a nonzero exit. Mark the check failed.
Diagnosis: inspect argument validation. The agent treated an unknown value as an empty match instead of an error. Ask for one scoped fix to validate accepted values before counting. Run the same invalid case and all earlier checks again.
Attempt 1: invalid status returned success, so acceptance failed.
Cause found: no accepted-value validation.
Attempt 2 request: reject unsupported values and retain 4/2/2 counts.
Evidence required: full test run and invalid command exit status.
Expected second result: a clear error and nonzero status for invalid, with unchanged valid counts. If the second run still fails, use the remaining retry only after naming a new cause. Repeating the same prompt is not diagnosis.
Handle Ambiguous Results
A process stopping without a result is not success. If a tool times out after a possible file write, inspect the files and Git status before rerunning it. If a connected service reports an unknown outcome, read its current state before retrying an external action. Duplicate sends, posts, or writes are a real risk outside the lab.
Stop for human review when the requirement conflicts with another approved source, a permission blocks the action, the retry budget ends, or the requested action crosses a publication boundary. The handoff should name the exact state and the choice needed.
Separate Loops from Monitors
An edit loop runs within a bounded task and checks after each action. A scheduled monitor wakes later to inspect a condition. A monitor needs its own cadence, change threshold, notification rule, and stop condition. Do not turn the lab edit loop into a recurring job. The next lesson evaluates persistent systems before enabling them.
Run a Controlled Loop
Start with the untouched lab. Its two baseline tests pass. Create tests/test_loop_contract.py in the fresh extraction with the check below. This file states a desired feature absent from the starter. It does not belong in the maintained starter ZIP.
"""One controlled failing check for the status-filter exercise."""

import subprocess
import sys
import unittest
from pathlib import Path

ROOT = Path(__file__).resolve().parents[1]


class LoopContractTests(unittest.TestCase):
    def test_open_status_count(self):
        result = subprocess.run(
            [sys.executable, str(ROOT / "task_report.py"),
             str(ROOT / "tasks.json"), "--status", "open"],
            capture_output=True, text=True, check=False,
        )
        self.assertEqual(result.returncode, 0, result.stderr)
        self.assertEqual(result.stdout.strip(), "Total tasks: 2")


if __name__ == "__main__":
    unittest.main()
Run python3 -m unittest discover -s tests -v. The two original tests should pass and the new contract test should fail because the starter lacks --status. Record the actual failure. If you initialized Git as shown in lesson 0, record git status --short too. Otherwise, compare changed files against an untouched extraction. On Windows, use py -3 if your setup used the launcher.
Set an action budget of three attempts: the first edit plus at most two corrections. Give your agent the loop contract above and ask for one scoped edit. After each attempt, inspect changed files, rerun all tests, and run the default, open, done, and invalid commands. Record the failure cause before another edit. Stop on a pass, an unrelated baseline failure, an out-of-scope change, or the third failed action.
Study route: apply the complete lesson 5 answer key in this fresh copy after recording the red test. Rerun the same checks and mark the agent edit not run. Keep the controlled contract test. Do not weaken or delete it to make the loop pass.
| Attempt | State and observation | Decision |
|---|---|---|
| Before edit | Two baseline tests pass, new open check fails | Proceed with one bounded edit |
| After each edit | Record exact tests, counts, invalid exit, changed files | Accept, diagnose, or stop |
| At budget end | Record remaining failure and current diff | Handoff without another retry |
Practice and Check
Your artifact: the controlled failing test, observed before and after test output, an attempt log, and a final accept or stop handoff. If the first edit passes, record one attempt. Do not invent a second failure to fill a log.
Completion check: the contract names a source, file scope, observable checks, retry limit, at least one immediate stop condition, and a handoff. Your record includes the real red test, the later check results, and either a passing result or a budget stop. A second attempt names a new cause and differs from the first.
Check Your Understanding
Question: What does the first red contract test prove? Answer: The starter lacks the requested status filter under a test written before the edit.
Question: When must the loop stop even with retries left? Answer: Stop for an out-of-scope change, unclear permission, or conflicting requirement.
Troubleshooting
- Loop repeats the same failure: stop and form a new cause hypothesis.
- Checks become weaker: restore the original acceptance checks.
- Uncertain external result: inspect current state before another action.
- Budget exhausted: hand off the failure record instead of hiding it.
Next Steps
Continue with Specialized Agent Evaluation for the optional lesson, or go straight to the AI Workflow Capstone . For broader runtime choices, read the site’s agent runtime guide .
Course navigation: Previous: Agent Delegation , Course outline .